Confidential by architecture
The model runs on your premises. During remote commissioning, we check with you that cloud model lanes are off.
DeepSenz Personal Agent · Premium
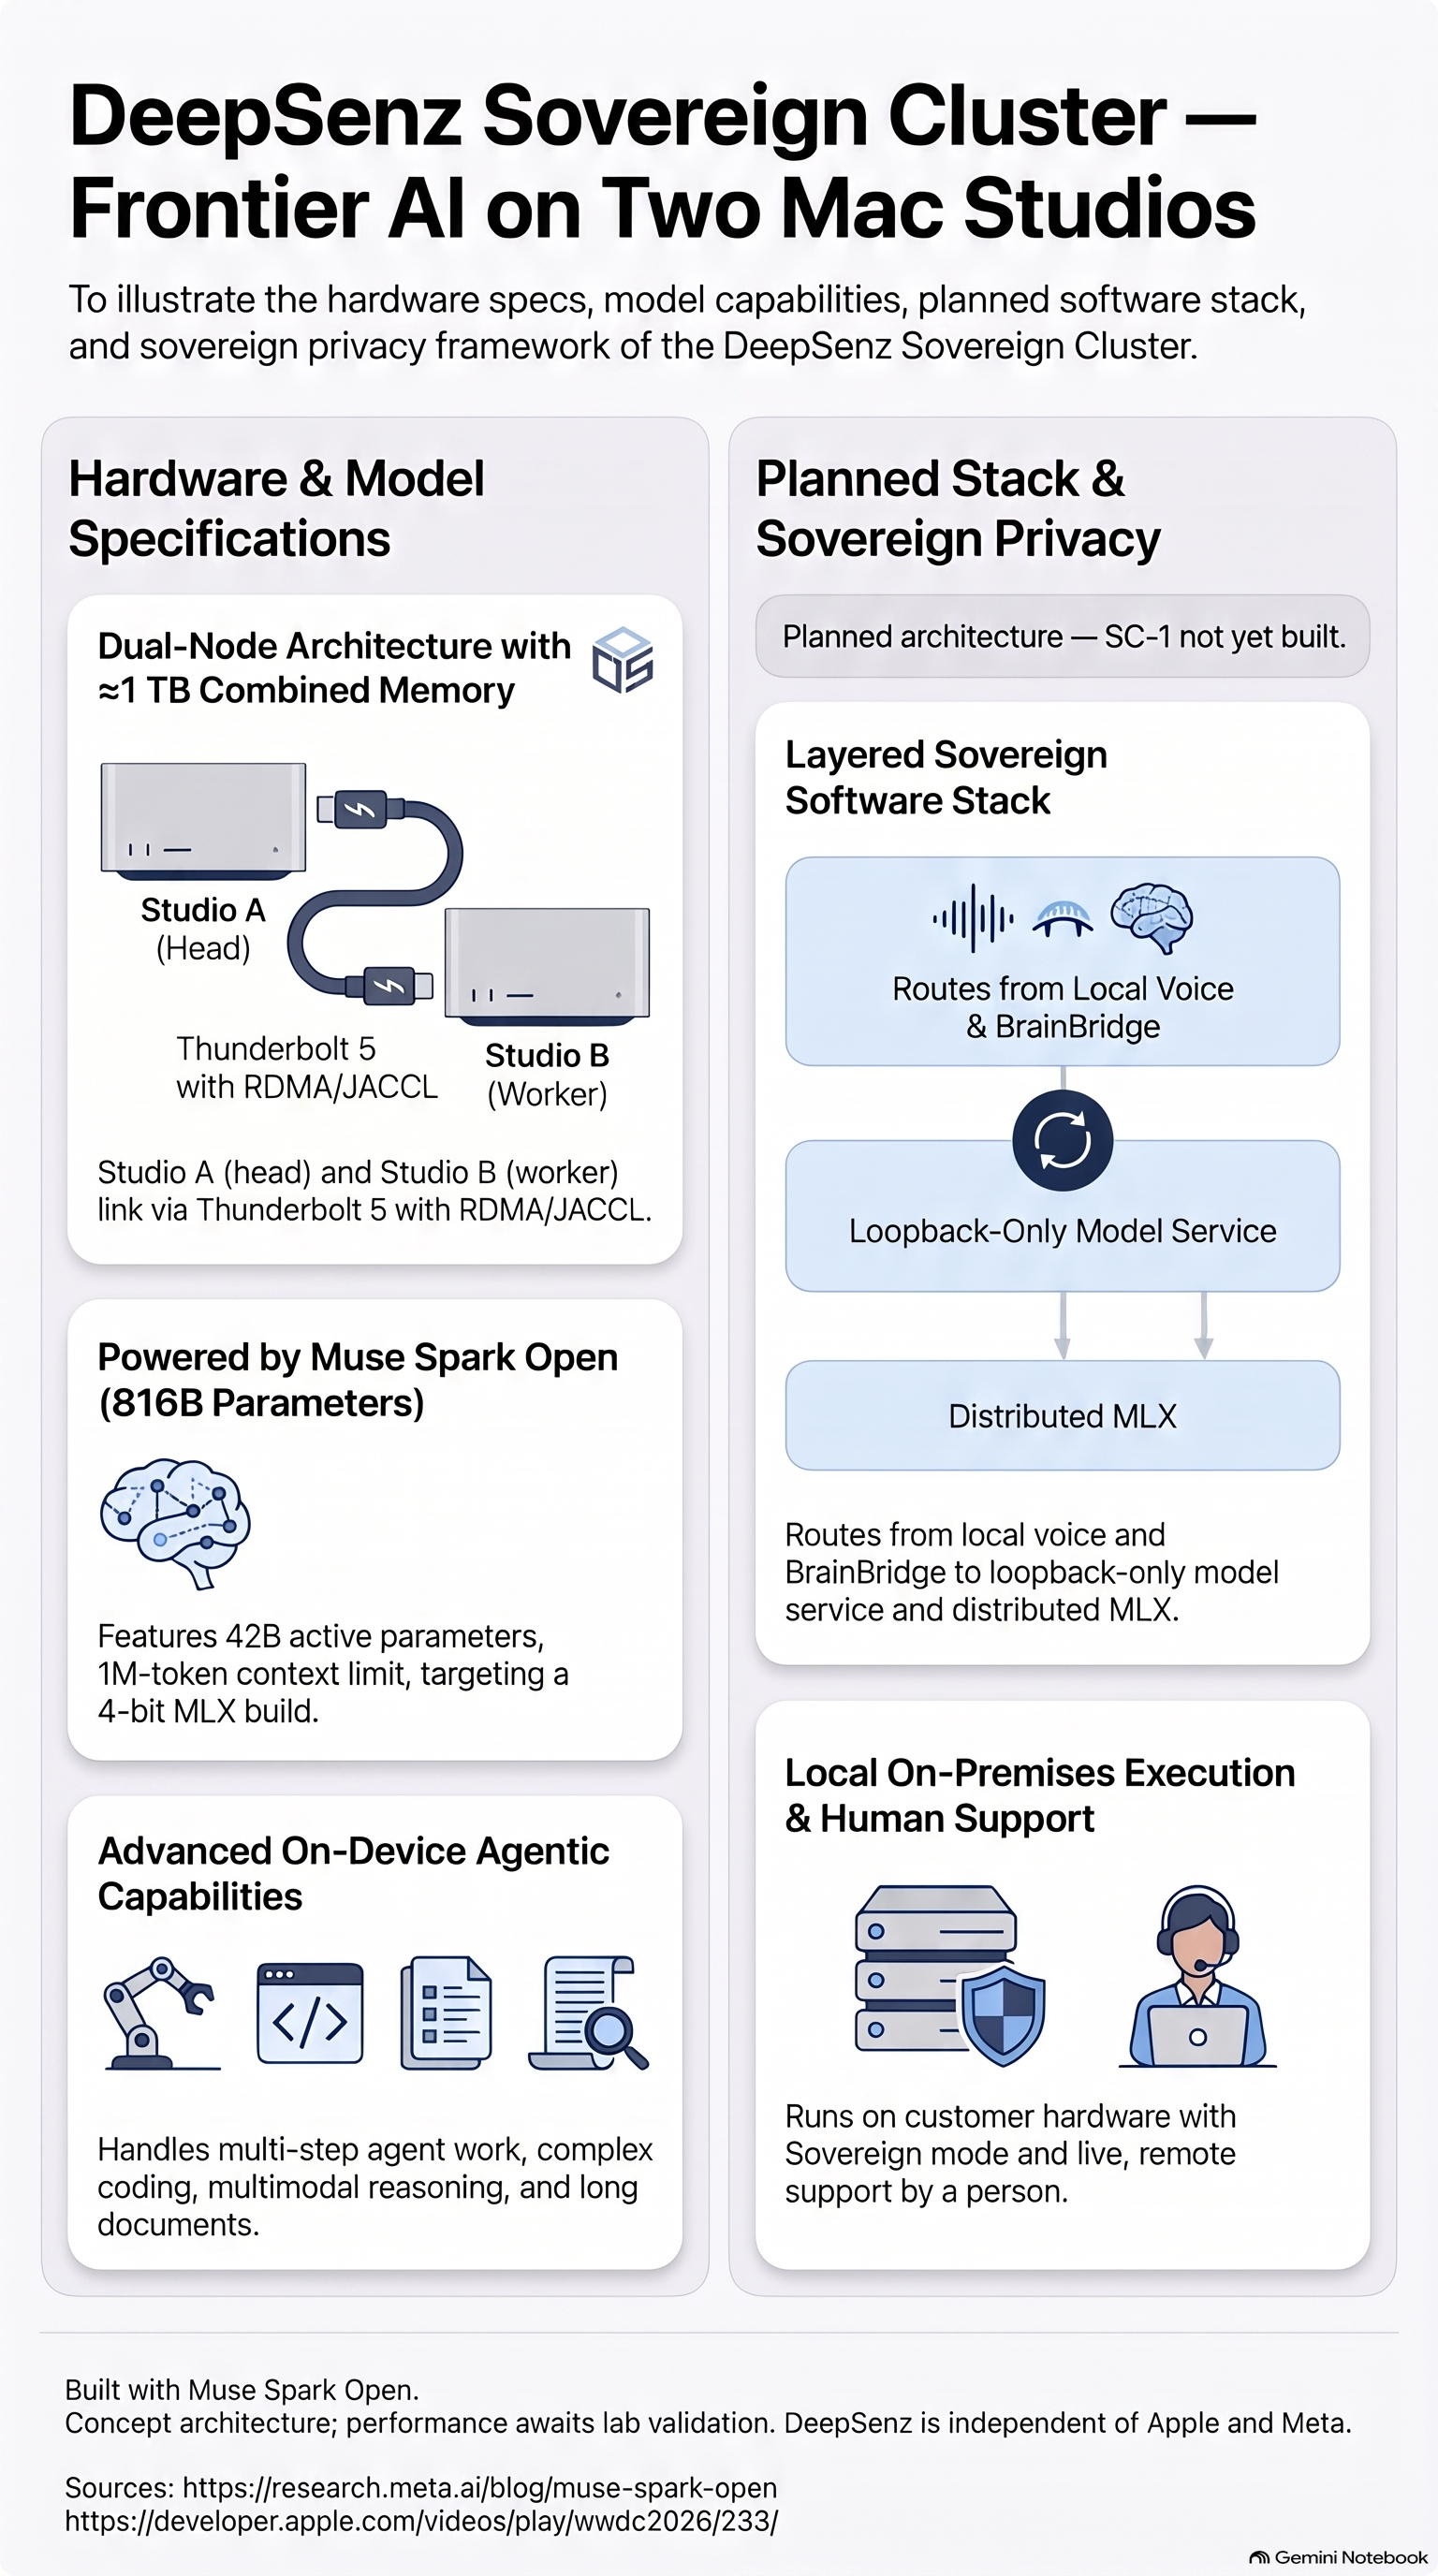
A proposed two-Mac-Studio Personal Agent powered by Meta's 816-billion-parameter Muse Spark Open model. DeepSenz will build and measure each installation before commissioning it with you. With local-only model routing, private prompts stay on your own machines; optional connected services remain your choice.
Online booking opens shortly. Please use the consultation form below.
Apple has demonstrated distributed Muse Spark Open inference on M5 Ultra Mac Studios with MLX. DeepSenz performance awaits our own lab validation.
Two-node architecture
Meta's 816-billion-parameter open-weight model can run locally through Apple MLX across two M5 Ultra Mac Studios. Each Mac can be configured with 512 GB of unified memory: 1,024 GB installed across two separate machines, connected for distributed inference over Thunderbolt 5.
Keep your agent available day and night while both Macs, power, and network are running. Requests served locally avoid metered cloud-model tokens; hardware, electricity, support, and any optional cloud routes still have costs.
Meta describes Muse Spark Open as the most capable US open-weight model to date. DeepSenz has not independently established an affordability ranking or measured this two-node build.
On-device capability
Apple demonstrated Muse Spark Open inference across two M5 Ultra Mac Studios using distributed MLX and Thunderbolt 5 RDMA. Each Mac supports up to 512 GB of unified memory. The two machines have 1,024 GB installed in aggregate, not a single shared memory pool. Apple's 1.2 TB/s figure describes memory bandwidth on each M5 Ultra chip, not memory capacity. Actual speed and power use for a DeepSenz installation still need lab measurement.
Who it's for
For founders, executives, family offices and professional practices (legal, medical, financial advisory) whose work is too confidential for any cloud.
The model runs on your premises. During remote commissioning, we check with you that cloud model lanes are off.
Long documents, complex analysis, coding and multi-step agent work on a model in the top tier of open-weight AI.
We build it, burn it in for 48 hours, guide you through setup remotely, teach you to use it, and provide live remote support from a human throughout the year.
What you get
How it works
Your use cases, your space, and the Muse license walkthrough.
Assembled and burned in at DeepSenz for 48 hours, with a measured performance report.
We guide you live as you connect the system, commission it remotely, and check with you that cloud model lanes are off.
We verify local model routing, review the handover pack with you, and show you how to run and stop the system. Deep Recall onboarding will be offered separately when available.
Quarterly live remote check-ins, tested updates, priority human support.
The complete system
From —
| Included | Estimated price |
|---|---|
| Estimated total | — |
The deposit is invoiced after discovery; no system payment is taken on this page.
Honest notes
We publish speed figures only after measuring them on our own lab cluster. The large model is built for depth, not instant chat; the everyday model handles quick replies. The model's long context limit is not a measured capacity for this two-node installation.
In Sovereign mode no request goes to a cloud model. You can choose to allow one later, on your own account, and switch it off at any time. Optional updates and connected services use the internet only with your approval.
The Muse Spark Open license does not permit use by anyone under 18, and it is not for operating critical infrastructure. The system is for your own use, not for reselling AI services to others.
A private conversation
We’ll discuss your work, your space, and the remote setup path. Brian will respond personally.
Prefer email? brian@deepsenz.ai